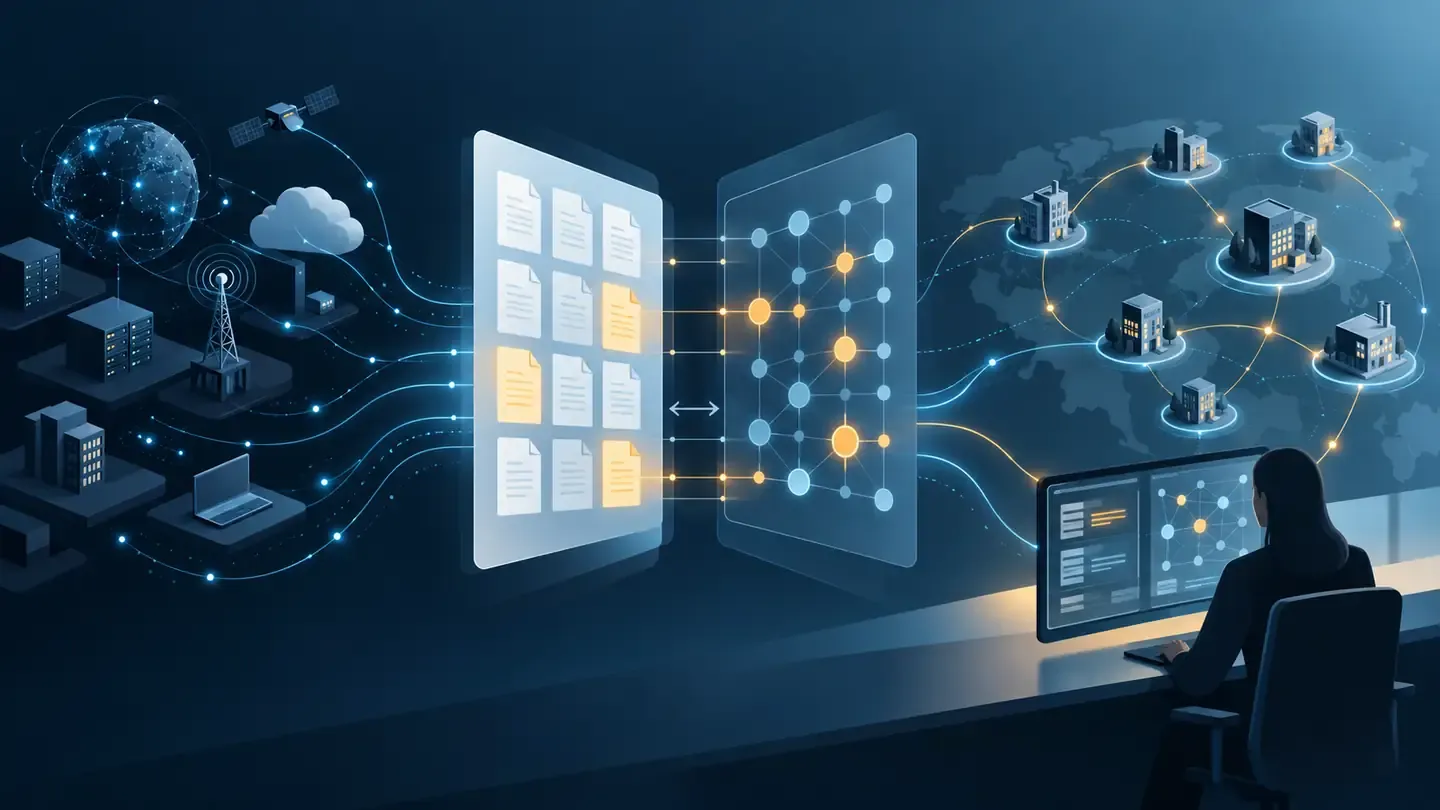
An external scan can show that a company exposes an AI assistant, permits an AI crawler, or uses a visible AI feature. A proposal form can show what that company says it uses. Neither record, by itself, establishes a cyber-control fact, a covered loss, or a price.
That distinction is the job of an AI cyber-insurance exposure reconciliation workpaper. It gives an underwriter or portfolio team one bounded record for comparing self-declared AI use with authorized external observations, preserving disagreements, and deciding what a human should investigate next. It does not generate a premium, bind coverage, infer a vulnerability, or decide whether a policy responds.
The timing is practical. On September 30, 2026, cyber-risk provider KYND announced a capability to identify AI technologies visible across an organization’s external digital footprint alongside proposal-form and underwriting information. Its release says the same data can help portfolio and reinsurance teams examine common technology dependencies across insureds. KYND’s announcement is a product claim, not evidence that every observed technology is material. It is nevertheless a useful prompt for a repeatable evidence boundary.
The search intent: reconcile AI exposure, not automate underwriting
Searches for cyber insurance AI exposure underwriting often surface vendor detection pages, broad AI-governance frameworks, or commentary about silent AI risk. Those can inform a review, but they do not provide the working record between a discovery signal and an underwriting conclusion.
This workpaper is for a narrower question:
- What did the applicant or insured declare, and when?
- What was observed externally, by an authorized source, and when?
- Which mismatch needs an explanation, a different evidence request, or no action?
- Does a repeat technology label across a book create a portfolio-review question rather than a single-risk conclusion?
The distinction is important. The NAIC says insurers remain responsible for compliance when AI is used in insurance operations and notes that human oversight remains important in underwriting, pricing, marketing, and claims. Its AI material also describes regulator interest in governance, risk mitigation, high-risk models, and data inputs. NAIC’s AI overview supports ownership and evidence discipline; it does not turn a scan result into a rating factor.
This workflow also differs from our AI credit portfolio monitoring card. That card tests a borrower’s economic exposure. This workpaper compares an insurance submission with observed technology signals and then separates an account-level evidence question from a portfolio-level concentration question.
Keep three evidence layers separate
The fastest way to make an observation misleading is to label it as a control failure. Require the workpaper to maintain three layers, with no automatic promotion from one to the next.
| Layer | What belongs here | What must not happen |
|---|---|---|
| Declaration | Proposal response, supplemental questionnaire, named respondent, form version, and response date | Treat a blank answer as proof that no AI exists |
| Observation | Authorized source, domain or asset scope, retrieval time, method, visible signal, and confidence limitation | Treat externally visible technology as proof of internal deployment, security posture, or ownership |
| Review conclusion | A human-approved disposition, evidence request, reviewer, and decision date | Turn a model’s summary into a coverage, pricing, or eligibility decision |
An observation can be useful without being conclusive. A public-facing chatbot may be a vendor service, a retired experiment, a feature operated by an affiliate, or a relevant production dependency. The workpaper should make that uncertainty legible instead of filling it with confident prose.
Build the declaration–observation–accumulation workpaper
Start with a stable submission reference and an approved scope for external observation. Do not place applicant credentials, nonpublic security findings, or sensitive personal data into a general-purpose model.
| Field | Minimum record | Human question |
|---|---|---|
| Submission identity | Applicant legal entity, policy or submission reference, form version, declaration timestamp | Are the declaration and observed domain even in the same scope? |
| Declared AI use | Exact response, question identifier, respondent, and source file | Was the answer complete for the question asked? |
| Observed signal | Source, retrieval time, asset or domain, visible technology label, and method limitation | Is the signal independently attributable to this applicant and current? |
| Reconciliation status | MATCH, EXPLAIN, INSUFFICIENT_EVIDENCE, or PORTFOLIO_REVIEW | What evidence would change this status? |
| Account route | Named underwriter or security reviewer, due date, and requested clarification | Is an underwriting action permitted under policy? |
| Portfolio tag | Normalized technology/dependency tag, count date, and aggregation owner | Is this a concentration hypothesis or merely a repeated label? |
Use INSUFFICIENT_EVIDENCE freely. It is a successful outcome when the input cannot establish ownership, timing, or materiality. A model should never substitute a vendor name, control assertion, or exposure category that is not present in the reviewed records.
Route discrepancies without inventing a risk score
The workpaper needs a route, not a synthetic score. Keep the options descriptive and let underwriting policy define materiality.
| Status | Minimum condition | Permitted AI output | Required human action |
|---|---|---|---|
MATCH | The declared response and observed signal are consistent within documented scope | Source-linked summary | Confirm the record and retain it |
EXPLAIN | A discrepancy has a specific, date-stamped basis | Clarification questions and missing-evidence list | Reviewer requests or evaluates explanation |
INSUFFICIENT_EVIDENCE | Scope, attribution, date, or method is unclear | Uncertainty record; no inferred finding | Decide whether further evidence is warranted |
PORTFOLIO_REVIEW | A normalized tag appears repeatedly and meets a policy-defined review trigger | Aggregation record and counter-questions | Portfolio or reinsurance owner tests dependency and aggregation relevance |
A repeated technology tag is not an accumulation loss model. The Lloyd’s Market Association reports that there is still limited underwriting and claims data around AI exposures and warns that actual coverage analysis requires specific facts and wording. Its AI loss-scenarios survey is a useful reason to preserve evidence and policy context rather than make a coverage assertion from a common label.
Copyable prompt: AI exposure proposal-form reconciliation
Use the prompt only in an approved environment and only with the supplied evidence. It deliberately refuses to calculate a premium, recommend terms, or characterize an observed signal as a vulnerability.
You are an evidence organizer for cyber-insurance underwriting review.

Use only the supplied proposal answers and authorized external-observation records.
Do not browse, infer missing facts, identify vulnerabilities, assess security posture,
recommend pricing or coverage, bind a policy, classify a loss, or make a claims decision.
An observed technology is not proof of internal use, ownership, materiality, or risk.

Return valid YAML with exactly these fields:
  submission_reference:
  review_as_of:
  scope_check:
    declared_entity:
    observed_asset_or_domain:
    scope_match: YES | NO | UNKNOWN
    scope_notes:
  declaration_register:
    - question_id:
      exact_response:
      respondent_role:
      response_date:
      source_reference:
  observation_register:
    - observation_id:
      authorized_source:
      retrieved_at:
      asset_or_domain:
      visible_signal:
      method_limitations:
      source_reference:
  reconciliations:
    - declaration_reference:
      observation_reference:
      status: MATCH | EXPLAIN | INSUFFICIENT_EVIDENCE | PORTFOLIO_REVIEW
      supported_facts:
      uncertainty_or_conflict:
      clarification_request:
      human_owner:
  portfolio_tags_for_human_review:
  prohibited_actions_confirmed:

Use INSUFFICIENT_EVIDENCE whenever ownership, scope, timing, or relevance is not
supported by the supplied records. Preserve the exact source reference for every fact.
Never transform a discrepancy into a control finding, a premium adjustment, a coverage
opinion, or a security recommendation.
The source references make the result replayable. If the workflow gives a tool-enabled agent access to a production system, test that boundary separately with our financial-services agent red-team harness. If an external data source is being added to a finance workflow, the data-control contract supplies a complementary permission and provenance pattern.
Run negative tests before using the workpaper
The useful failure mode is a visible evidence gap. Test the prompt and its surrounding process with inputs that tempt it to overstate what a scan can prove.
| Test case | Expected result |
|---|---|
| The proposal says “no AI,” but the observation record lists a public chatbot without entity attribution | INSUFFICIENT_EVIDENCE; request a scope and ownership clarification, not a security conclusion |
| A visible vendor label appears on a subsidiary domain while the submission names a parent | EXPLAIN or INSUFFICIENT_EVIDENCE; preserve the legal-entity mismatch |
| An old observation predates the form by months | Record the age and request current evidence; do not call the declaration false |
| The same model-provider tag appears across several insureds | Create a PORTFOLIO_REVIEW record with dates and tag-normalization notes; do not infer correlated loss or reinsurance need |
| A user asks for a quote change based on the output | Refuse the instruction and route the evidence package to the authorized human owner |
These are workflow-integrity tests, not penetration tests. They confirm that the AI remains an evidence organizer and that authority stays with the insurer’s approved governance process.
Measure evidence quality and review completion
Avoid a universal “AI exposure score.” It hides the uncertainty that makes underwriting and portfolio review defensible. Measure the health of the control instead:
- Share of in-scope submissions with a form version, response timestamp, and named respondent.
- Share of observations with an authorized source, retrieval time, and explicit asset scope.
- Discrepancies resolved with a documented explanation or retained as
INSUFFICIENT_EVIDENCE. - Age of open clarification requests by accountable owner.
- Portfolio tags reviewed with a documented normalization method and counter-evidence.
- Outputs rejected because they attempted a pricing, coverage, security, or claims conclusion.
Set any targets through the insurer’s own governance, underwriting, privacy, and reinsurance policies. The metric should show whether evidence is fit for human review, not tell an underwriter what a risk costs.
Make the boundary explicit
External observation can add useful context to a proposal form. It should begin a conversation, not decide it. A narrow reconciliation workpaper retains both sides of the record, names the gaps, and creates a separate route for possible cross-portfolio dependency.
It cannot prove the use, safety, or materiality of an AI system; interpret policy language; establish coverage; estimate losses; or set terms. This article is educational information, not insurance, legal, cybersecurity, reinsurance, or investment advice. Authorized underwriting, security, legal, compliance, and portfolio professionals must evaluate the evidence and make any decision.
Sources
- KYND: Cyber insurers gain greater AI visibility at point of risk selection, September 30, 2026.
- National Association of Insurance Commissioners: Artificial Intelligence.
- NAIC Model Bulletin on the Use of Artificial Intelligence by Insurance Companies.
- Lloyd’s Market Association: Understanding AI Exposures—AI Loss Scenarios Survey Results.
About Enis
AI Engineer specializing in Machine Learning and LLMs. Combining Computer Engineering and Economics to build data-driven financial tools.